For teams where everyone builds their own brain
You want every agent run to be better than the last, for you, and your customers.
Compound with Clarity.
Right now every person builds their own local brain — and the company keeps siloing its intelligence. Clarity stacks every personal harness into one compounding company brain, in your walled garden.
Company brain is a Clarity API pilot for source-connected decisions and scoped context reuse. Explore the pilot · Compare the distinct offers
01 / 05 · THE SILOS
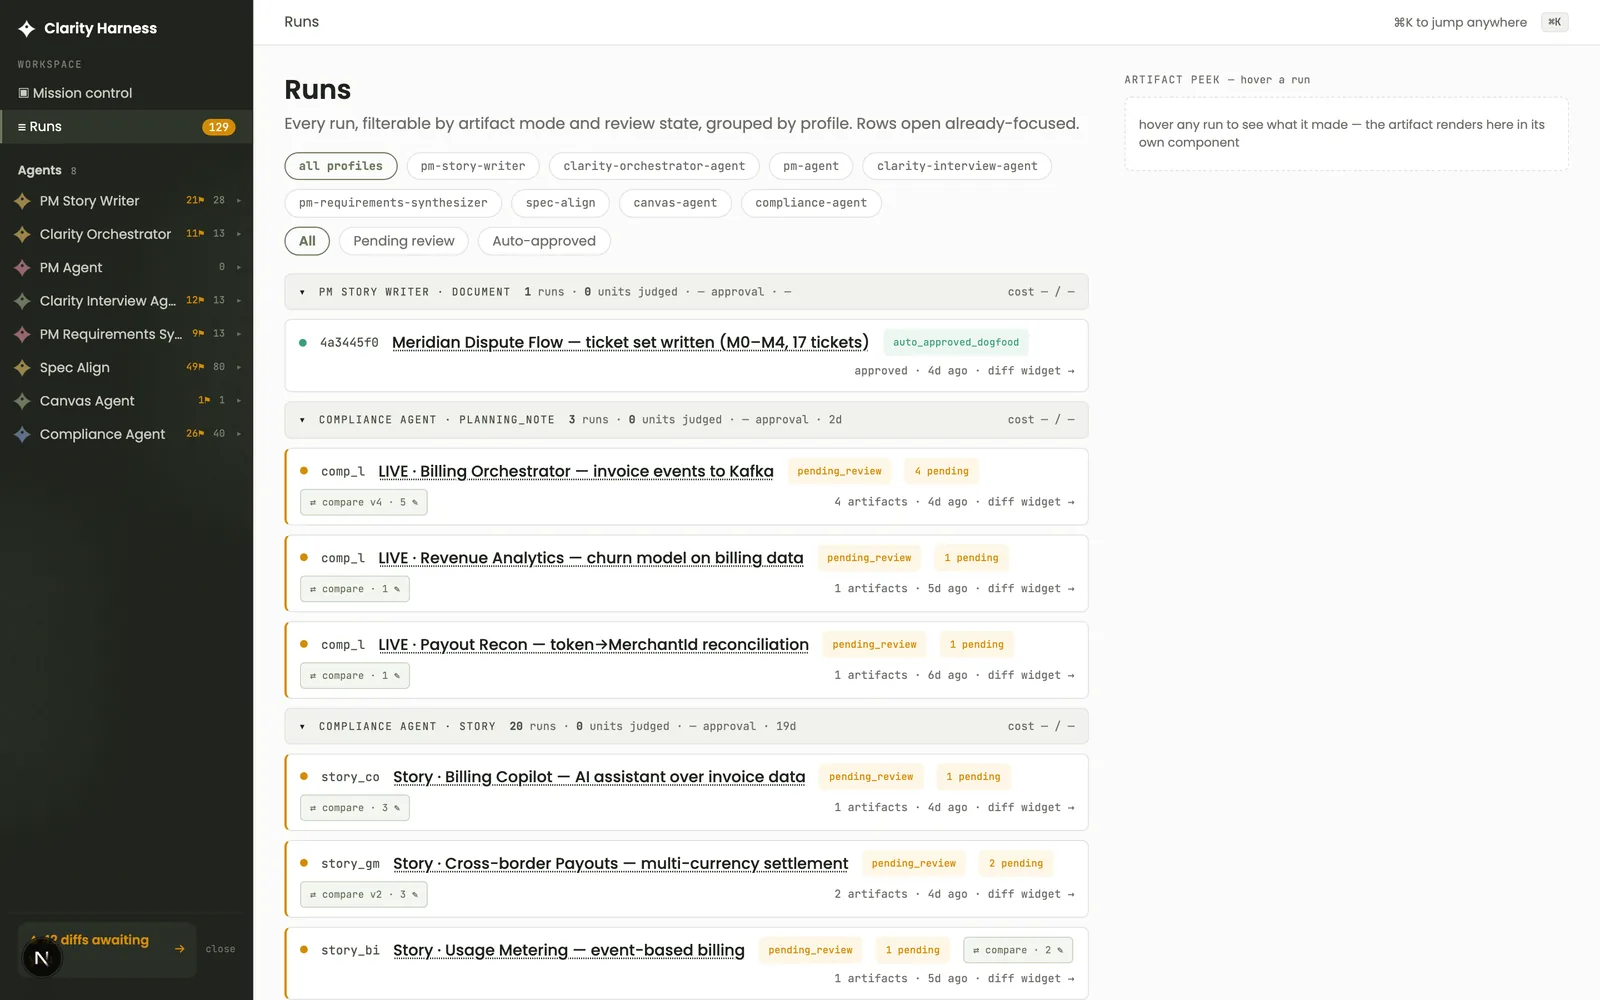
Every run captured — and owned by the company.
A plugin sits beside the coding agent each person already uses. Every run it sees lands in one harness, with the verdict that judged it.
02 / 05 · YOUR N = 1 HARNESS
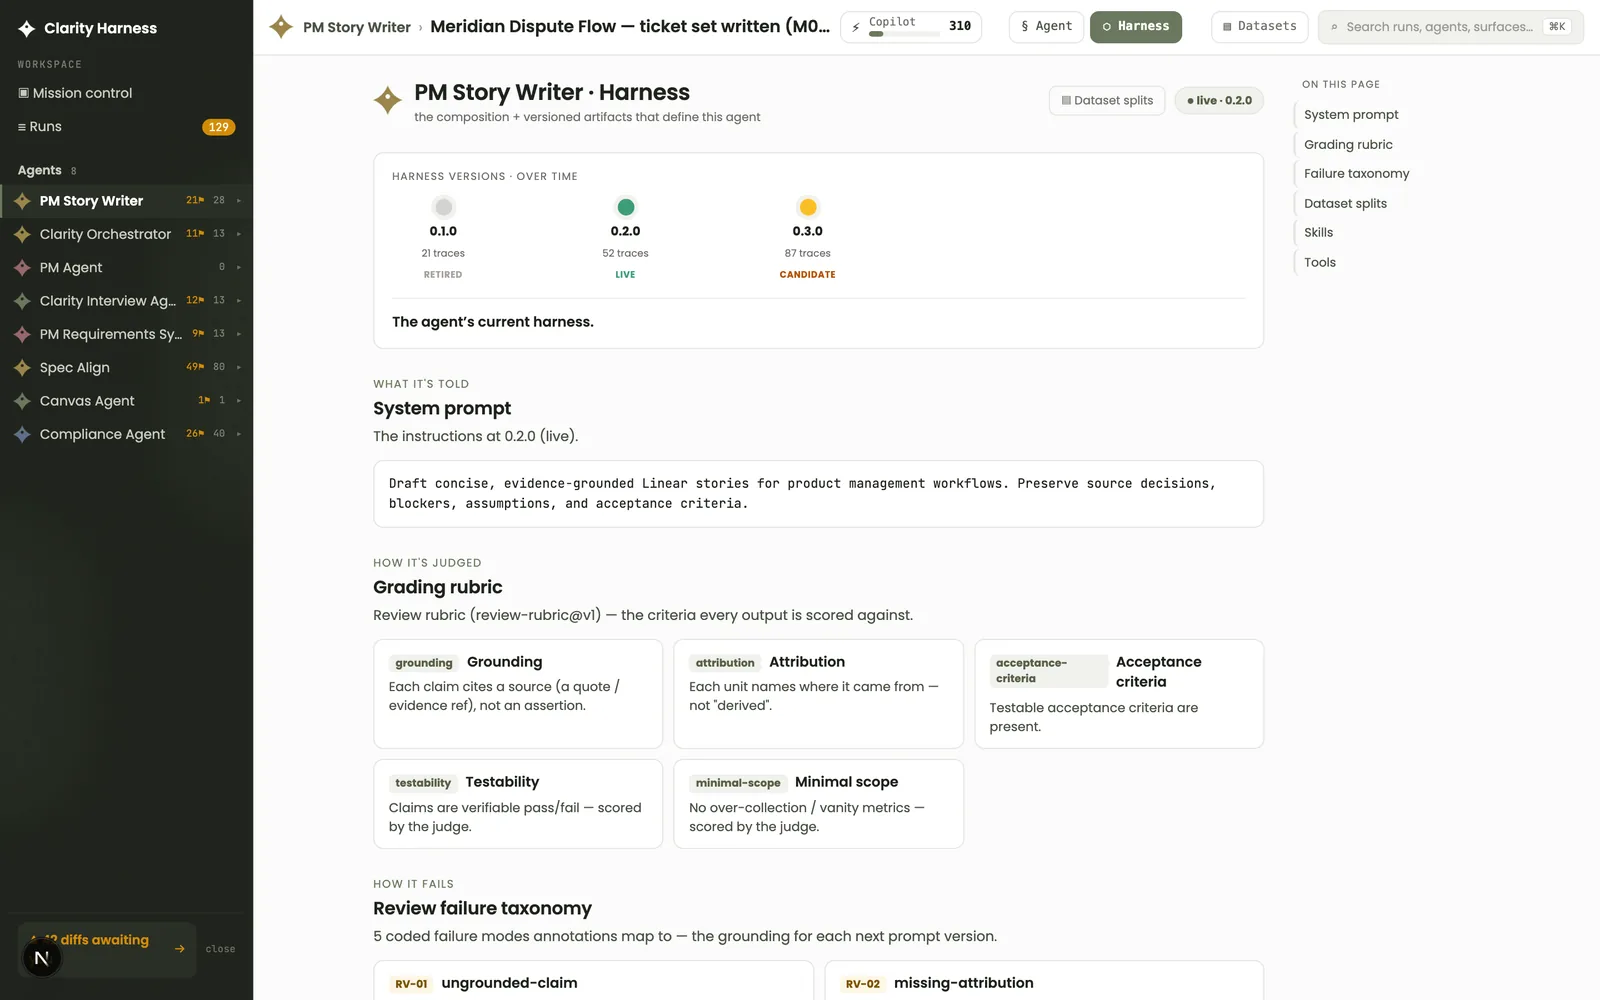
A harness shaped like the person using it.
Clarity builds a digital twin of each person — their goals, their judgment, their taste — so your harness is n = 1, not one-size-fits-all.
03 / 05 · THE STACKED HARNESS
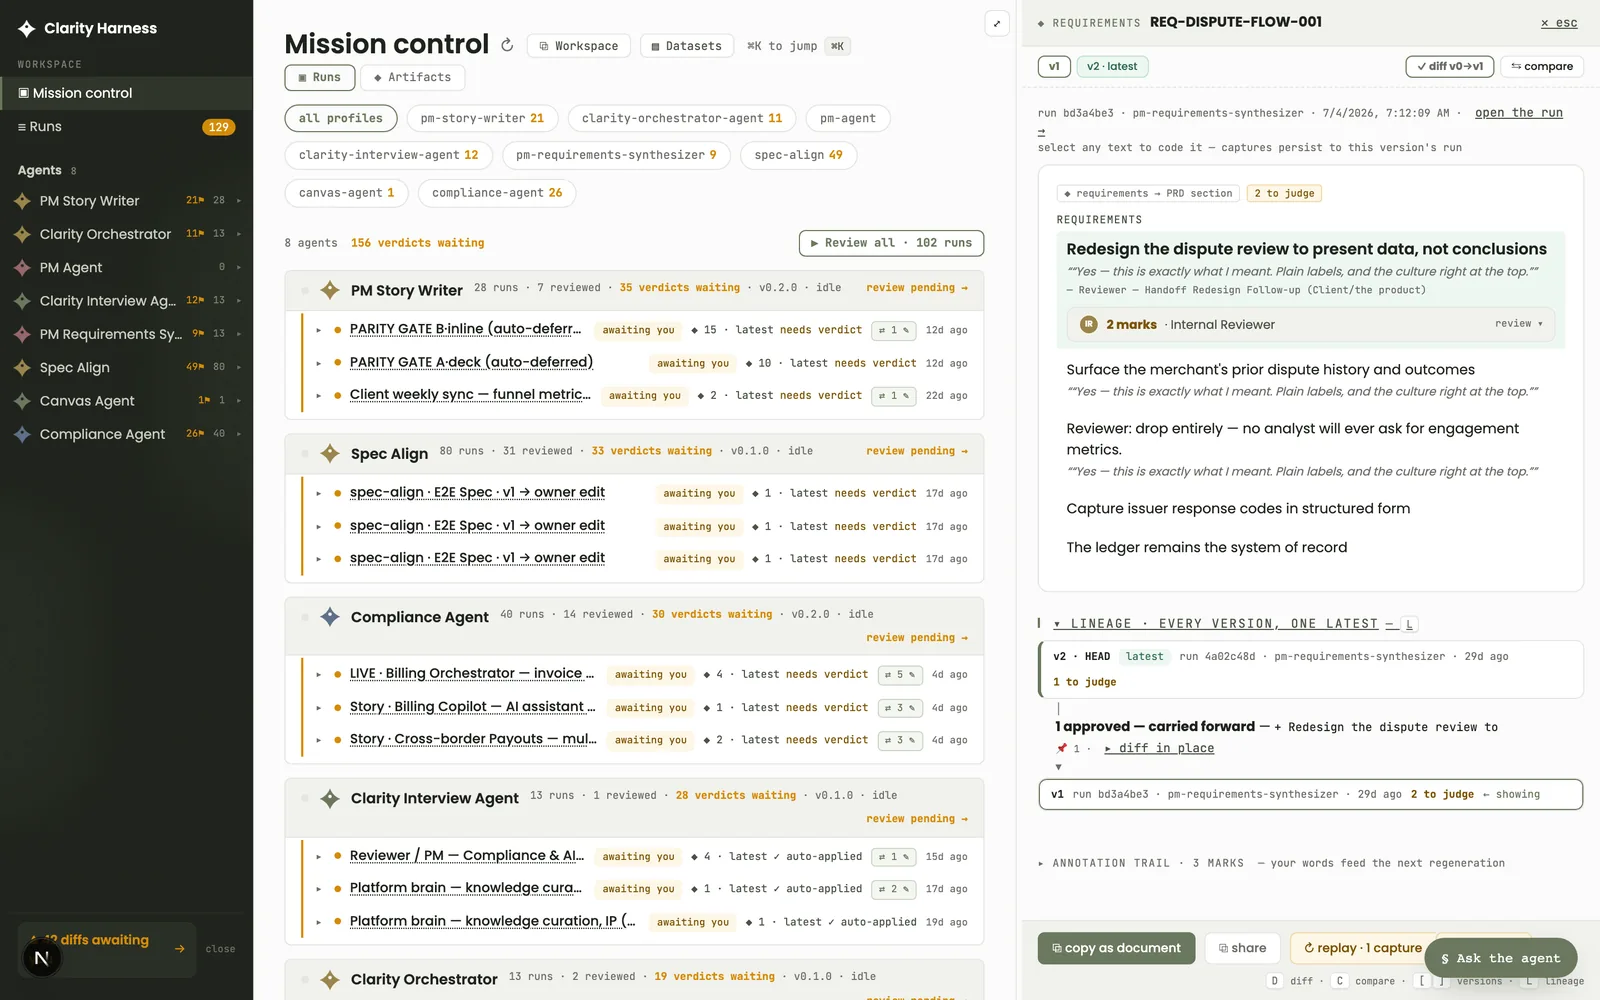
What one agent learns helps the next.
Each agent has context, tools and checks. Review a useful lesson, then share it with team and company context where permissions allow. The next agent can reuse the lesson.
Personal agent · context + tools + checks
04 / 05 · PRIVATE EVALS
Private evals your company owns.
Every verdict becomes a reusable private eval — intellectual property that compounds, so a day-one teammate works like a day-365 one.
05 / 05 · YOUR WALLED GARDEN
Your company brain lives in your walled garden.
Self-hosted: a Postgres database in your own cloud. Model-agnostic, cloud-agnostic, and bring your own observability — if your traces already live somewhere, the harness meets them there.
Scroll to explore · illustration of permitted learning
Old world · 01
Everyone builds their own local brain.
- Context, skills and corrections stay on one laptop
- None of it reaches the people next to you
- The company keeps siloing its intelligence
New world · 01
Every run captured — and owned by the company.
A plugin sits beside the coding agent each person already uses. Every run it sees lands in one harness, with the verdict that judged it.
Capture the run
Old world · 02
Every harness looks the same.
- Everyone runs nearly the same harness
- You can’t shape it to how you think
- Different roles, one-size-fits-all setup
New world · 02
A harness shaped like the person using it.
Clarity builds a digital twin of each person — their goals, their judgment, their taste — so your harness is n = 1, not one-size-fits-all.
Carry personal judgment
Old world · 03
A shared skill is a fraction of a harness.
- Skills get passed around without their context
- They half-work for everyone else
- Nobody knows which version actually worked
New world · 03
What one agent learns helps the next.
Each agent has context, tools and checks. Review a useful lesson, then share it with team and company context where permissions allow. The next agent can reuse the lesson.
Build · Product · Review agents → Team → Company
Personal agent → human review → team → company → next agent
Illustration: review a source correction, approve its sharing scope, then reuse it across permitted agents.
Old world · 04
Your judgment walks out the door.
- Expert taste lives in heads, not systems
- Generic evals don’t know your domain
- Day one looks nothing like day 365
New world · 04
Private evals your company owns.
Every verdict becomes a reusable private eval — intellectual property that compounds, so a day-one teammate works like a day-365 one.
Bank reviewed judgment
Try it — judge a real run
MER-508 Chargeback evidence packet — assembled from the dispute timeline
Old world · 05
Your data can’t leave the building.
- Third-party memory means third-party risk
- Locked to one model, or one cloud
- Yet another observability stack to adopt
New world · 05
Your company brain lives in your walled garden.
Self-hosted: a Postgres database in your own cloud. Model-agnostic, cloud-agnostic, and bring your own observability — if your traces already live somewhere, the harness meets them there.
Keep knowledge within your boundary
Speed without compounding is just expensive slop.
The promise
Every verdict compounds.
The harness closes the loop: capture the run, deploy the agent, review with a verdict, learn from the correction. Today's annotation is tomorrow's default. Week one feels like review. Week six feels like leverage.
- CaptureEvery run recorded, receipts attached
- DeployThe agent runs your workflow
- ReviewYou give the verdict in minutes
- LearnCorrections banked into the next run
The promise
Every verdict compounds.
The harness closes the loop: capture the run, deploy the agent, review with a verdict, learn from the correction. Today's annotation is tomorrow's default. Week one feels like review. Week six feels like leverage.
Capture
Every run recorded, receipts attached
Deploy
The agent runs your workflow
Review
You give the verdict in minutes
Learn
Corrections banked into the next run
Capture
Every run recorded, receipts attached
Deploy
The agent runs your workflow
Review
You give the verdict in minutes
Learn
Corrections banked into the next run
Proof
We've helped real businesses with AI — from YC startups to $2B companies.
We can help you too.
The Harness direction · coming soon
Clarity Harness. Free OSS, coming soon.
The full harness UI
Mission control, run views, judgment queue — the exact interface in the screenshots above.
Runs with receipts
Every run recorded: source input, agent chain, tool calls, decisions taken and not taken.
The verdict system
Approve, edit, reject, defer — annotations persist as structured data, not Slack threads.
Versioned datasets
Corrections become a dataset with lineage — dev, staging, prod — that regenerates your agents better.
MCP serve
Point Claude Code or any coding agent at your harness — orchestrator calls the agent, agent calls the skill.
Our setup playbook
The internal guide we used to stand up our own harness. Release scope and timing are not yet announced.
Free OSS Clarity Harness is coming soon. AI-native services start at $100k+. Clarity API enterprise pilots for company brain and hyper-personalization are custom quoted. Explore company brain.
Built in the open
A community for builders who believe agents deserve better than vibes.
The harness ships free and open source because the thesis is bigger than a tool. This is the Clarity bet — and we're building a community of AI builders who share it:
◆
Subjectivity is the missing primitive
Autonomy doesn’t come from bigger models. It comes from knowing whose goals, whose judgment, and whose context a run answers to.
◆
Alignment is layered
Individual, team, and organization goals aren’t the same thing — a real harness reconciles all three instead of pretending one prompt covers it.
◆
Closed loops beat bigger prompts
True autonomous agents are grown, not prompted: run → verdict → learn → run again, with the human judgment banked every cycle.
If that's your thesis too, don't just star the repo — come build the loop with us.
Scaling past your own harness? Company-wide harnesses are the layer we build with design partners — see the company brain →
Clarity API enterprise pilots · Custom quote
Join the company-brain pilot waitlist.
Explore a scoped company-brain API pilot for your people and agents. Scope, integration and evaluation criteria are agreed for the pilot.
Discuss a custom-quoted API pilot →
Clarity API pilots are custom quoted